
Document automation with AI integration is often presented as a simple conversion from PDF to text. In a real business workflow, extraction is only one stage. The useful result is a controlled path that receives a document, identifies its type, extracts the required fields, checks them against business rules, asks for human review when confidence is insufficient and sends approved data to the correct system.
Invoices, orders, contracts, request forms and email attachments can arrive in different layouts and with uneven quality. A reliable solution therefore combines conventional validation, optical character recognition, AI interpretation and a review interface. No single component should be expected to solve every case.
The goal is not to remove people from the process at any cost. It is to remove repetitive transcription while keeping responsibility visible wherever an error could affect money, customers, compliance or an operational decision.
Key ideas in this article
- OCR converts visible content into machine-readable text, but it does not complete the business process.
- A robust workflow combines AI interpretation with deterministic rules and source-system checks.
- Confidence scores should determine review priority, not silently authorize important actions.
- The review screen must show the source, extracted field and reason for uncertainty together.
- Accuracy should be measured by document type and field, alongside processing time and correction rate.
OCR, intelligent extraction and workflow automation are different layers
OCR recognizes characters in scans and images. It can turn a photographed invoice into text, but it does not necessarily know that one number is a tax identifier, another is an invoice total and a third belongs to a purchase order. Intelligent document processing adds classification and field interpretation. Workflow automation decides what happens after those fields are checked.
This distinction matters when comparing products or estimates. A demonstration that recognizes text can look impressive while leaving employees to locate the correct file, rename it, verify every value, enter it into the ERP and resolve exceptions manually. The complete result must be evaluated from intake to the final system action.
A complete document flow has explicit control points
A production flow starts by accepting documents from approved channels such as an upload form, a monitored mailbox, a scanner or an API. It checks file type, size, malware status and duplication before processing. The file is then prepared, classified and sent through the appropriate extraction method.
Extracted values pass through format checks and business rules. A supplier code can be compared with the supplier registry, an invoice total can be reconciled with line items and a contract date can be checked against an allowed interval. Cases that fail or remain uncertain enter a review queue. Only approved data should update the CRM, ERP, accounting platform or document system.
- Receive and register the original file with a unique identifier.
- Run technical, security and duplicate checks.
- Classify the document and select the correct extraction profile.
- Extract fields while retaining their location in the source.
- Validate formats, relationships and external references.
- Route uncertain or high-impact cases to a person.
- Commit approved information and preserve an audit trail.
Choose documents with repeatable value, not only impressive variety
Good first candidates have sufficient volume, recurring fields and a clear destination. Supplier invoices, purchase orders, delivery documents, standard request forms, service reports and recurring contract types are easier to evaluate than an unrestricted archive of unrelated files.
A company should count monthly volume, average manual handling time, correction frequency and the operational impact of delay. A low-volume document that takes two minutes to enter may not justify a complex integration. A recurring form that blocks a whole approval chain may justify it even at lower volume.
Documents used for employment, credit, insurance, health or other sensitive decisions require additional legal and operational scrutiny. Automation should not conceal the criteria or remove a meaningful review path.
Use rules where the answer must be exact
AI is useful when layouts and language vary. Conventional code is stronger when a field must match an exact pattern, a sum must reconcile or a user must have a specific permission. A healthy design assigns each type of work to the mechanism that can be tested most clearly.
For example, AI can identify which paragraph describes a termination period. The application can then require a person to confirm that paragraph before storing the value. A tax number should be validated by format and, when appropriate, by an authoritative source rather than accepted because the model considers it plausible.
A confidence score is a routing signal, not proof
Providers can return confidence values for classifications and extracted fields, but those values do not have one universal meaning. They must be calibrated with the company documents and the cost of each type of error. A threshold suitable for a searchable archive may be unacceptable for payment instructions.
The system can automatically accept low-impact fields above a tested threshold, request review for medium-confidence results and reject unreadable cases. High-impact values may require confirmation regardless of confidence. Thresholds should be revised using real corrections after launch.
Human review must be designed as part of the product
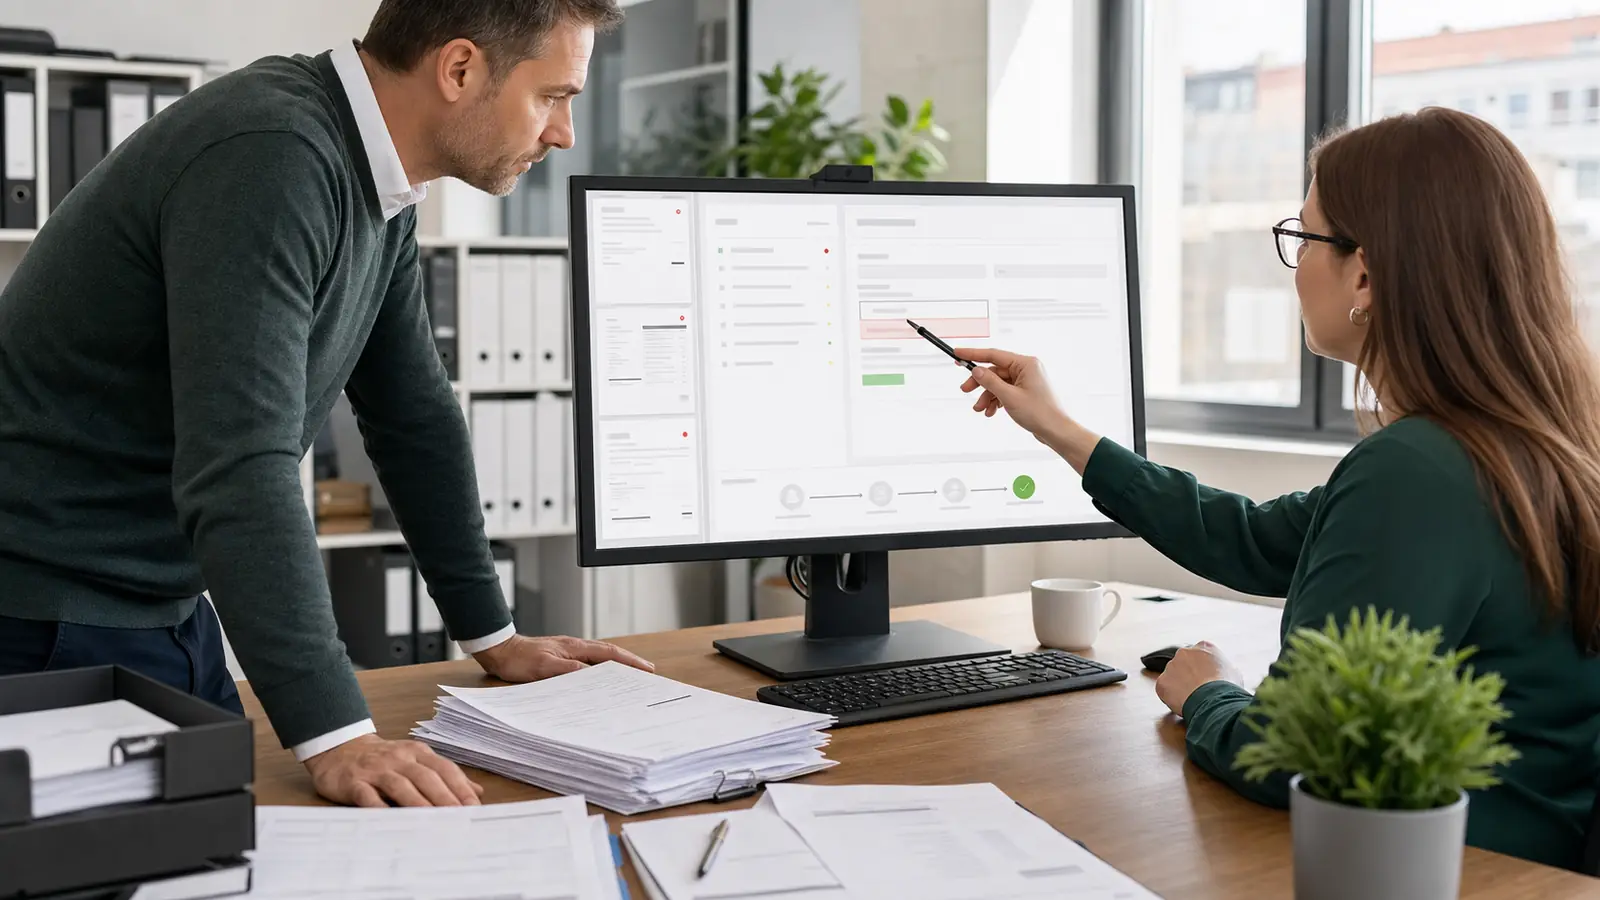
A review queue is not useful when the operator has to open three systems and reconstruct why a document was flagged. The interface should display the original page, highlight the source area, place the proposed value nearby and explain which validation failed. Keyboard navigation and bulk handling can matter when volume is high.
Review actions should distinguish correction, rejection and escalation. The application should record who approved a result and what changed, but avoid turning every small correction into a burdensome ceremony. The amount of friction should follow the impact of the decision.
Decide which system owns the final information
Document automation often touches a CRM, ERP, accounting product, shared drive and reporting layer. One system must remain authoritative for each important field. Otherwise, the automation can create several slightly different versions of the same supplier, amount or status.
Integration design should specify field mapping, update direction, duplicate behavior, retry rules and what happens when the destination is unavailable. A failed write must not be reported as a completed document. Reprocessing should be possible without creating a second transaction.
Treat document content as untrusted input
A document can contain confidential data, malicious files or instructions that attempt to influence an AI component. The application should scan uploads, restrict file types, isolate processing and never allow text found inside a document to change permissions or tool access.
Credentials belong in protected configuration, not in prompts or documents. Access to originals and extracted data should follow user roles. Retention periods, deletion and provider settings must be decided before the archive grows into an uncontrolled secondary data store.
Measure quality at field level
One global accuracy percentage can hide serious weaknesses. The solution should report results by document type and by important field: how often it was extracted, automatically accepted, corrected, rejected or left empty. Monetary values, identifiers and dates often deserve separate thresholds.
Operational metrics should include median processing time, queue age, percentage handled without intervention, average review time, integration failures and cost per processed document. These numbers show whether the system reduces work rather than merely moving it to another screen.
Start with a representative pilot
A useful pilot uses a restricted document family and a sample that includes clean files, scans, unusual layouts and known exceptions. The team defines mandatory fields, acceptable error rates and the actions that remain blocked until review. Historical documents can create the initial evaluation set without exposing the workflow to customers immediately.
The pilot should end with a decision: expand, adjust the process, change the extraction approach or stop. A prototype that has no threshold and no owner can remain permanently in demonstration mode without proving operational value.
Common questions
A document does not need one fixed template for automation to work, but recurring families and fields make quality easier to measure. Highly variable files usually require more classification and review.
Handwritten content can sometimes be recognized, although quality depends heavily on language, image quality and handwriting. It should be tested separately rather than included in a general promise.
Automatic posting to accounting or payment systems is technically possible, but the authorization level should reflect financial impact. Extraction and approval are separate decisions.
The original file should normally be retained according to an explicit policy because extracted fields do not preserve every visual or legal detail of the source.
Official technical references
- Google Cloud: Document AI overview
- Microsoft Learn: Azure AI Document Intelligence
- AWS: Amazon Textract documentation
The strongest document automation does not promise perfect extraction. It builds a measurable route from an untrusted file to verified information and a controlled business action.
