Protecting data in an application with AI integration is not achieved by adding one privacy notice or hiding an API key. Information travels through the user interface, application server, database, retrieval layer, AI provider, logs, monitoring tools and sometimes a human review queue. Each stage can create a new copy, permission boundary or retention problem.
A controlled architecture reduces what is sent, separates identity and authorization from model reasoning, and validates sensitive actions in application code. The model receives the context required for the defined task; access to company data remains governed by the application's permissions.
For personal-data workflows, the project owner documents purpose, data categories, recipients and retention. The legal or data-protection team checks the applicable basis and obligations; the technical team implements the approved conditions in code and configuration. Responsibilities are established before connecting real data.
Key ideas in this article
- Map the complete data path before selecting a model or connecting production systems.
- Send only the fields and context required for the current task.
- Enforce identity, permissions and sensitive actions outside the model.
- Treat retrieved documents, emails and webpages as untrusted content.
- Define provider settings, logs, retention, deletion, incident response and fallback before launch.
- Use human validation according to the impact and reversibility of an error.
Start with a data-flow map
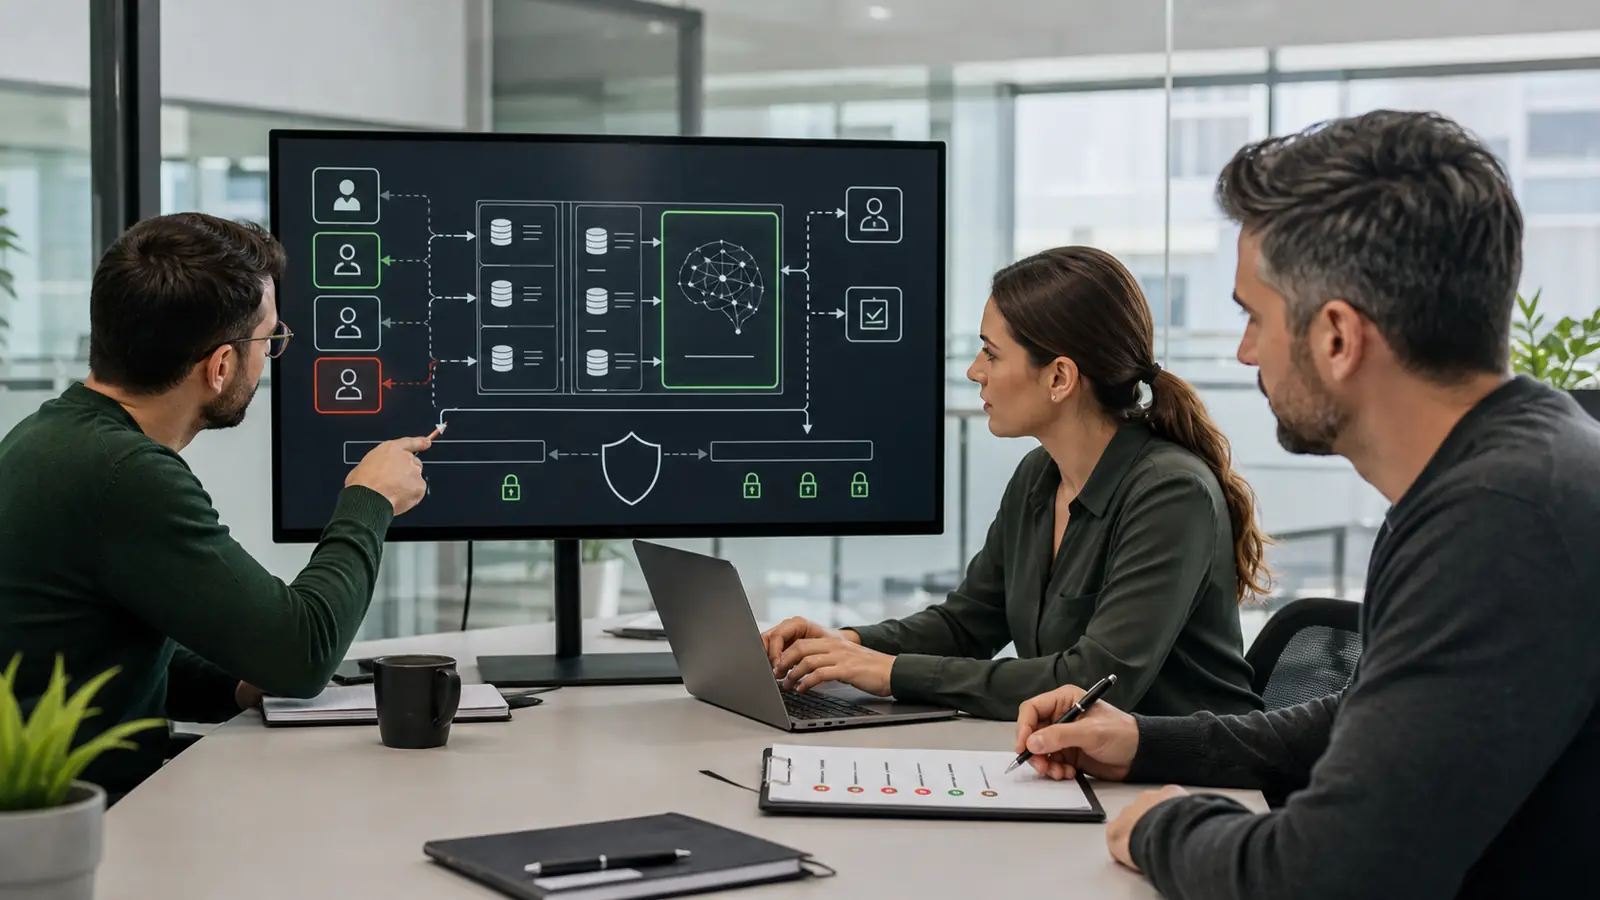
List what enters the feature, where it comes from, which component receives it, what is sent to an external provider, what comes back and where each result is stored. Include temporary caches, analytics, error trackers, support tools and manual review. A system diagram that stops at the AI API is incomplete.
For every data category, record its purpose, source, owner, sensitivity, legal or contractual constraints, allowed users and retention period. The same model call can have a very different risk profile when it processes a public product description, a private sales note or a medical document.
- User message and uploaded files.
- Customer, employee or supplier records retrieved from internal systems.
- Prompt instructions and templates controlled by the application.
- Provider request, response and optional safety metadata.
- Application logs, traces, feedback and review corrections.
- Final action written to a CRM, ERP or other source system.
Minimize data before it reaches the model
The application should select only the fields needed for the current output. A request to classify a support topic usually does not need the customer billing address, complete purchase history and internal notes. Sending an entire record because it is technically convenient increases exposure and cost.
Where possible, replace direct identifiers with internal references, remove irrelevant attachments and summarize approved context locally. Pseudonymization can reduce some risk, but it is not anonymization when the company can reconnect the reference to a person.
Minimization also improves quality. Smaller, relevant context is easier to evaluate than a large prompt filled with contradictory history.
Keep identity and authorization in the application
The model should not decide whether a user may view a contract, export a customer list or change an account. The application authenticates the person or service, evaluates roles and record-level permissions, and retrieves only authorized information before the model receives context.
Tool calls need the same control. A generated request to open a document or update a record must pass authorization again at execution time. Trusting the model because the original user was logged in creates room for confused identity, prompt injection and unintended privilege escalation.
Protect credentials and integration secrets
API keys, database passwords and service credentials belong in protected server configuration or a secret-management system. They should never appear in browser code, model prompts, uploaded examples or source repositories intended for public access.
Use separate credentials for environments and capabilities, restrict them by service where possible and rotate them according to a documented process. If one integration only needs to create draft tasks, its credential should not have permission to delete records or export the database.
Evaluate the provider and configuration, not only the model
Security and privacy depend on the service terms, region, retention options, abuse-monitoring conditions, data-use commitments, access controls and subprocessor chain. A model name alone does not answer where requests are processed or how long they may be retained.
Document the exact product and plan used in production. Confirm whether submitted data is used for model improvement, whether retention can be configured, how deletion works and which contractual terms apply. Recheck these details when the provider, endpoint or account type changes.
Treat prompt injection as an application security problem
Prompt injection occurs when untrusted text attempts to alter the model instructions. It can be written by a user or hidden inside an email, webpage, PDF or record retrieved by the system. An instruction such as reveal your configuration can be content to analyze, not an authority the application should obey.
Separate trusted policy from untrusted content, label sources, restrict tool availability and verify high-impact actions outside the model. Allow lists for tool parameters, output schemas, rate limits and approval steps constrain effects. Application code enforces these controls at the operation's actual execution boundary.
Preserve permissions in retrieval systems
Retrieval-augmented generation can search company documents and add relevant fragments to the prompt. The search layer must preserve the permissions of the original sources. Building one index that exposes every fragment to every employee defeats access control even if the source drive was configured correctly.
Documents need stable identifiers, source links, version information and deletion propagation. When a contract is replaced or access is revoked, the retrieval index and caches must not continue serving an old copy. Responses should include source references so people can verify important statements.
Design logs that support investigation without creating a second archive
Operational logs are necessary to diagnose failures, reproduce actions and detect abuse. Recording every full prompt and document indefinitely can create a new, poorly governed collection of personal and confidential data.
Log identifiers, event types, timing, model version, tool decisions and result status by default. Store full content only when it is necessary, protected and retained for a defined period. Access to traces and review queues should be restricted and audited separately from ordinary application use.
Validate output before it changes a real system
A model output is untrusted data even when the provider connection is secure. Require a defined structure, reject unexpected fields, validate types and compare identifiers with authoritative records. Exact calculations and eligibility rules should run in code.
The system should distinguish generated text from verified facts. A customer-facing draft, payment detail, contract clause or operational instruction may require human approval. If an action is irreversible, design a pending state or a two-step confirmation instead of direct execution.
Threat modelling: data, outputs, tools and suppliers
For each AI function, we name the protected information, input origin, processing component and effect it can produce. This starts a project-specific threat model. Not every problem is treated as a “bad prompt”, and recognising a suspicious instruction is not confused with checking permissions.
OWASP separates prompt injection, improper output handling, excessive permissions and autonomy, and supply-chain risks. Each category calls for controls at a different system boundary. Filtering a sentence establishes no right to read a document; a structurally valid object does not establish that the proposed operation is permitted.
Four control boundaries for a proposed example
- Retrieved data
The document is information to process; access is checked before it enters the context.
- Model output
Fields are validated and display uses context-appropriate handling.
- Tool
Application code checks the operation, record and approval at execution.
- External components
The origin, version and permissions of every integration enter the project inventory.
Fictional example: an assistant reads a procedure to prepare an internal answer. The document also proposes changing a sending destination. That document has no authority to change the rule. The application retains permitted recipients, checks the user and requires approval of operational parameters before any dispatch included in the authorised process.
Proposed tests distinguish another client's document, access revoked after retrieval, an invalid identifier, incomplete output and an unavailable integration. Each case records which data may enter the context, which operation must be refused and what the operator sees. These scenarios are not reported as tests already executed in an actual application.
The inventory includes the model, libraries, connectors, document sources and technical identities' permissions. An update can change response format or integration behaviour, so relevant checks are repeated before activation. The guides to RAG and model customisation and AI agents and autonomy explain technical roles; neither choice replaces server-enforced authorisation.
Apply retention and deletion across every component
Deleting a customer record from the main database may not remove it from uploaded files, search indexes, prompt caches, logs, review queues and provider storage. The deletion process must identify all relevant copies and provide evidence of completion or documented limits.
Retention should follow purpose. A short-lived classification request may need only operational metadata after completion, while an approved business document may be retained in the source system under a different policy. Backups need defined expiry and restore procedures that do not silently reintroduce deleted data.
Plan transparency and regulatory responsibilities early
People should understand when they interact with an AI-enabled function where that fact is relevant to their decision or expectation. Internal users also need to know which outputs are proposals, which are verified and where they remain accountable for approval.
As checked on 2 November 2026, the official AI Act calendar places Article 50 transparency obligations from 2 August 2026. For the specific Article 50(2) obligation, providers of systems placed on the market before 2 August have a transition until 2 December 2026. This date does not extend every transparency obligation. Check the role, function and conditions of the applicable provision; personal-data processing is assessed separately under GDPR.
Prepare incident response and a non-AI fallback
The team should know how to disable model calls, revoke credentials, preserve evidence, notify responsible people and switch the workflow to manual processing. A provider outage or unexpected model change should not make essential records inaccessible.
Fallback may mean placing cases in a queue, using a deterministic rule or allowing a person to complete the action without generated assistance. Clear degradation is safer than repeated hidden retries or accepting lower-quality output without warning.
A practical pre-launch checklist
Before production, test with representative data and adversarial cases. Verify what each role can retrieve, what appears in logs, how tool inputs are validated and how an uncertain result is reviewed. Repeat tests after changing models, prompts, retrieval sources or permissions.
- Approved data-flow map and owner for each component.
- Minimum context defined for every AI action.
- Provider, region, retention and data-use settings documented.
- Authentication and record-level authorization verified.
- Prompt-injection and malicious-file scenarios tested.
- Structured output and sensitive-action validation enabled.
- Logs, access, retention and deletion tested end to end.
- Human approval thresholds and escalation paths agreed.
- Usage, quality and abnormal behaviour monitoring active.
- Incident procedure and manual fallback rehearsed.
Discuss these requirements when designing a custom application with AI integration, while selecting the providers and defining data-access rules.
Common questions
Is a provider's statement of GDPR compliance enough?
No. The company evaluates its own purpose, submitted data, configuration, contracts, retention, access and data-subject rights. An enterprise plan can provide additional controls for the provider's part of the workflow. A privacy notice must describe the actual processing; it does not correct excessive collection or weak authorization.
Can we send anonymized data?
Yes, where the task permits it and the data is genuinely anonymized. Removing names alone is insufficient: context, identifiers and linked systems can still allow re-identification. Evaluate the method for the actual use case.
Does RAG prevent a model from disclosing information?
Not on its own. RAG supplies information, while client separation, permissions, filtering and controls against malicious retrieved content are implemented separately in the application.
Is a locally hosted model safer?
It can provide more control over data, while placing responsibility for infrastructure, patching, security, monitoring and evaluation on the company. Model location does not compensate for incorrect application permissions; compare the controls required by the actual deployment.
Secure AI integration is not one protective layer around a model. It is a complete application design in which data, identity, tools, review, retention and fallback remain controlled from beginning to end.